publications
My research focuses on Argument Mining, fallacy detection, and political debate analysis. Publications listed in reverse chronological order.
2026
-
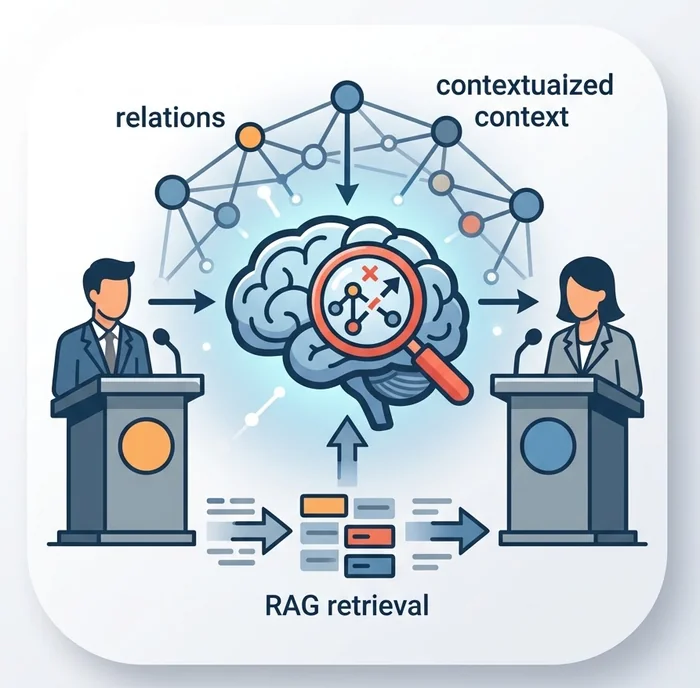 Retrieving Relations, Detecting Fallacies: A RAG Approach To Political Debate AnalysisDeborah Dore, Greta Damo, Elena Cabrio, and Serena VillataIn , 2026Under review at EACL 2027
Fallacies are arguments that employ invalid reasoning, making their automatic detection critical in sensitive contexts such as high-stakes political debates, where public opinion is shaped. Spotting a fallacious argument requires contextual knowledge beyond its pure surface text. This entails world knowledge pertaining to the subject matter under discussion, as well as knowledge of the relationships that exist between arguments within the argumentative discourse. Prior work on fallacy analysis has shown that argumentative discourse structure can beneficially improve classification performance. However, such structure is typically encoded only as static classifier features, limiting its flexibility. Building on this intuition while addressing this limitation, we introduce a guided retrieval-augmented methodology for fallacy detection and classification that leverages argumentative relations of support and attack to dynamically steer the extraction of relevant documents. We evaluate our approach on the ElecDeb60to20 benchmark across 42 retrieval configurations and 14 models, performing retrieval over a 15GB knowledge base of collected political-related documents. Our approach improves macro-F1 up to 0.864 for fallacy detection and up to 0.725 for classification over non-retrieval baselines. These results show that incorporating external knowledge significantly enhances fallacy detection and classification when retrieval is argumentatively guided.
-
 RooseBERT: A New Deal For Political Language ModellingDeborah Dore, Elena Cabrio, and Serena VillataIn The 25th IEEE/WIC International Conference on Web Intelligence and Intelligent Agent Technology (WI-IAT 2026), Brisbane, Australia, 2026
The increasing amount of political debates and politics-related discussions calls for the definition of novel computational methods to automatically analyse such content with the final goal of lightening up political deliberation to citizens. However, the specificity of the political language and the argumentative form of these debates (employing hidden communication strategies and leveraging implicit arguments) make this task very challenging, even for current general-purpose pre-trained Language Models (LMs). To address this, we introduce a novel pre-trained LM for political discourse language called RooseBERT. Pre-training a LM on a specialised domain presents different technical and linguistic challenges, requiring extensive computational resources and large-scale data. RooseBERT has been trained on large political debate and speech corpora (11GB) in English. To evaluate its performances, we fine-tuned it on multiple downstream tasks related to political debate analysis, i.e., stance detection, sentiment analysis, argument component detection and classification, argument relation prediction and classification, policy classification, named entity recognition (NER). Our results show significant improvements over general-purpose LMs on the majority of these tasks, highlighting how domain-specific pre-training enhances performance in political debate analysis.
-
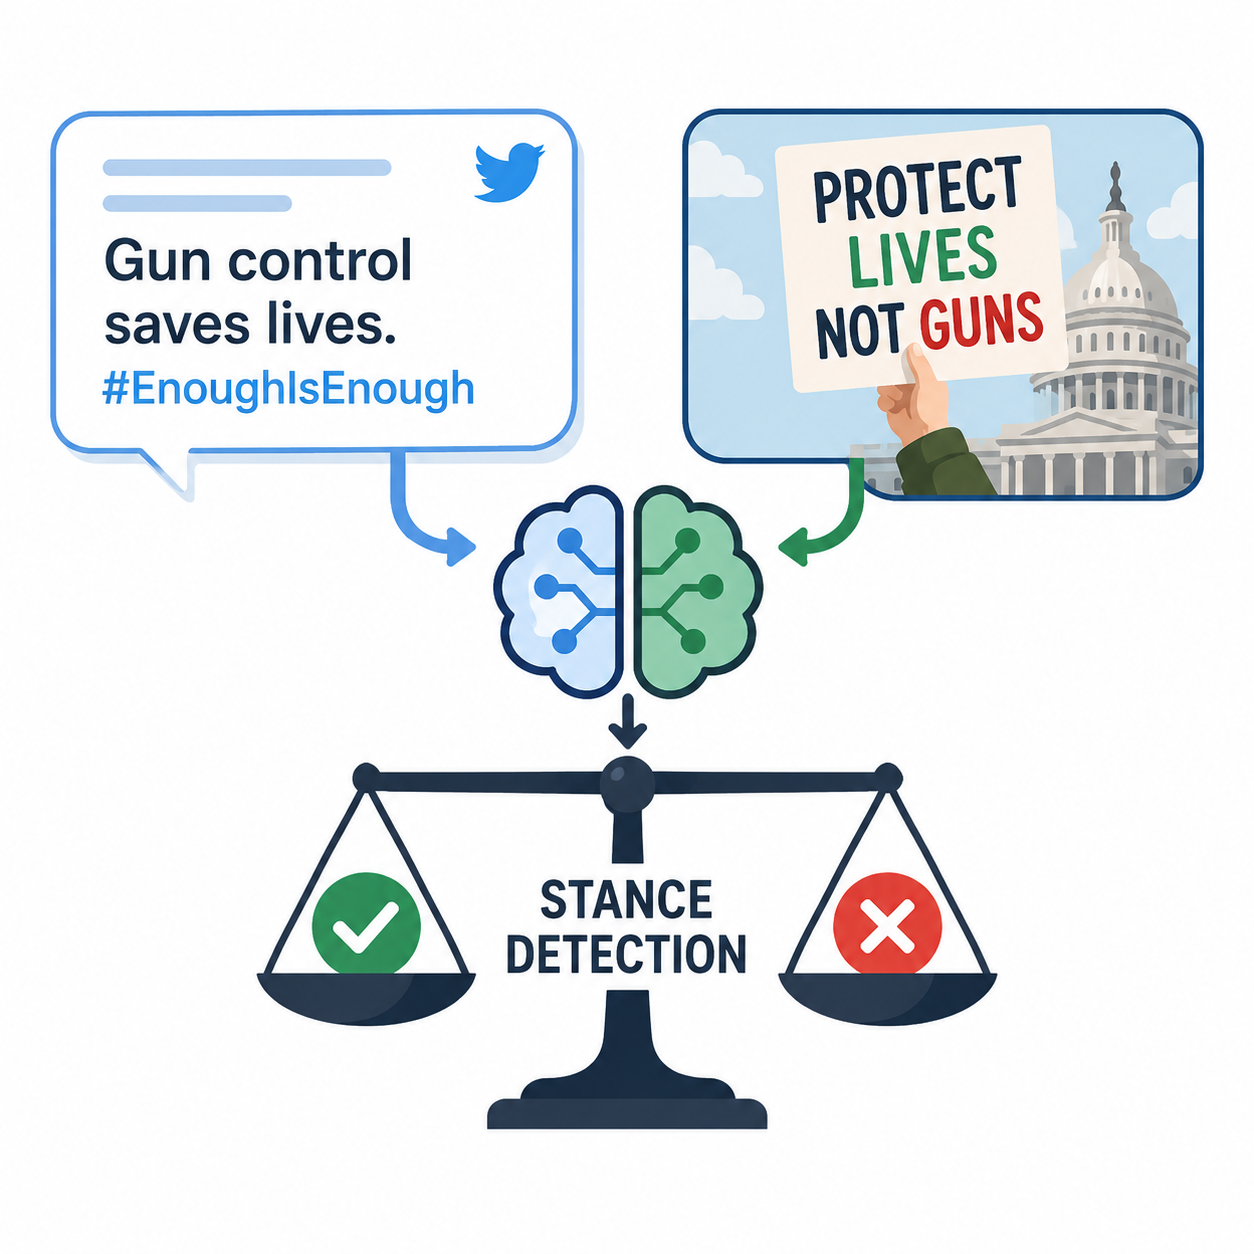 Multimodal Stance Detection in Controversial TweetsDeborah Dore, Diego Blassio, Elena Cabrio, and Serena VillataIn 11th International Conference on Computational Models of Argument (COMMA 2026), Barcelona, Spain, 2026
Multimodal Argument Mining aims at combining different modalities (i.e., text, image, video, audio) to achieve a better understanding of verbal and non-verbal argumentation. Despite significant progress in extracting and analysing argumentation structures from text, few approaches have addressed the challenge of combining different modalities in this analysis. This remains a highly unexplored but urgent topic, given the increasing impact of multimedia data in society. In this paper, we tackle this question by proposing a multimodal approach to the stance detection task. Starting with the ImageArg-2023 shared task dataset, which comprises tweets paired with images on the controversial topics of abortion and gun control, we propose the following contributions: \textiti) we present an updated version of the ImageArg dataset where we fixed some issues ensuring a high Inter-Annotator Agreement, and \textitii) we propose a modular architecture for multimodal stance detection which outperforms SoA approaches on this task. In addition, we quantify and discuss how each modality contributes to the classification task. This allows us to gain a better understanding of the role that each modality plays in multimodal AM.
2025
-
 Leveraging Graph Structural Knowledge to Improve Argument Relation Prediction in Political DebatesDeborah Dore, Stefano Faralli, and Serena VillataIn Proceedings of the 12th Workshop on Argument Mining, ArgMining 2025, Vienna, Austria, July 31, 2025, 2025
Argument Mining (AM) aims at detecting argumentation structures (i.e., premises and claims linked by attack and support relations) in text. A natural application domain is political debates, where uncovering the hidden dynamics of a politician’s argumentation strategies can help the public to identify fallacious and propagandist arguments. Despite the few approaches proposed in the literature to apply AM to political debates, this application scenario is still challenging, and, more precisely, concerning the task of predicting the relation holding between two argument components. Most of AM relation prediction approaches only consider the textual content of the argument component to identify and classify the argumentative relation holding among them (i.e., support, attack), and they mostly ignore the structural knowledge that arises from the overall argumentation graph. In this paper, we propose to address the relation prediction task in AM by combining the structural knowledge provided by a Knowledge Graph Embedding Model with the contextual knowledge provided by a fine-tuned Large Language Model. Our experimental setting is grounded on a standard AM benchmark of televised political debates of the US presidential campaigns from 1960 to 2020. Our extensive experimental setting demonstrates that integrating these two distinct forms of knowledge (i.e., the textual content of the argument component and the structural knowledge of the argumentation graph) leads to novel pathways that outperform existing approaches in the literature on this benchmark and enhance the accuracy of the predictions.
-
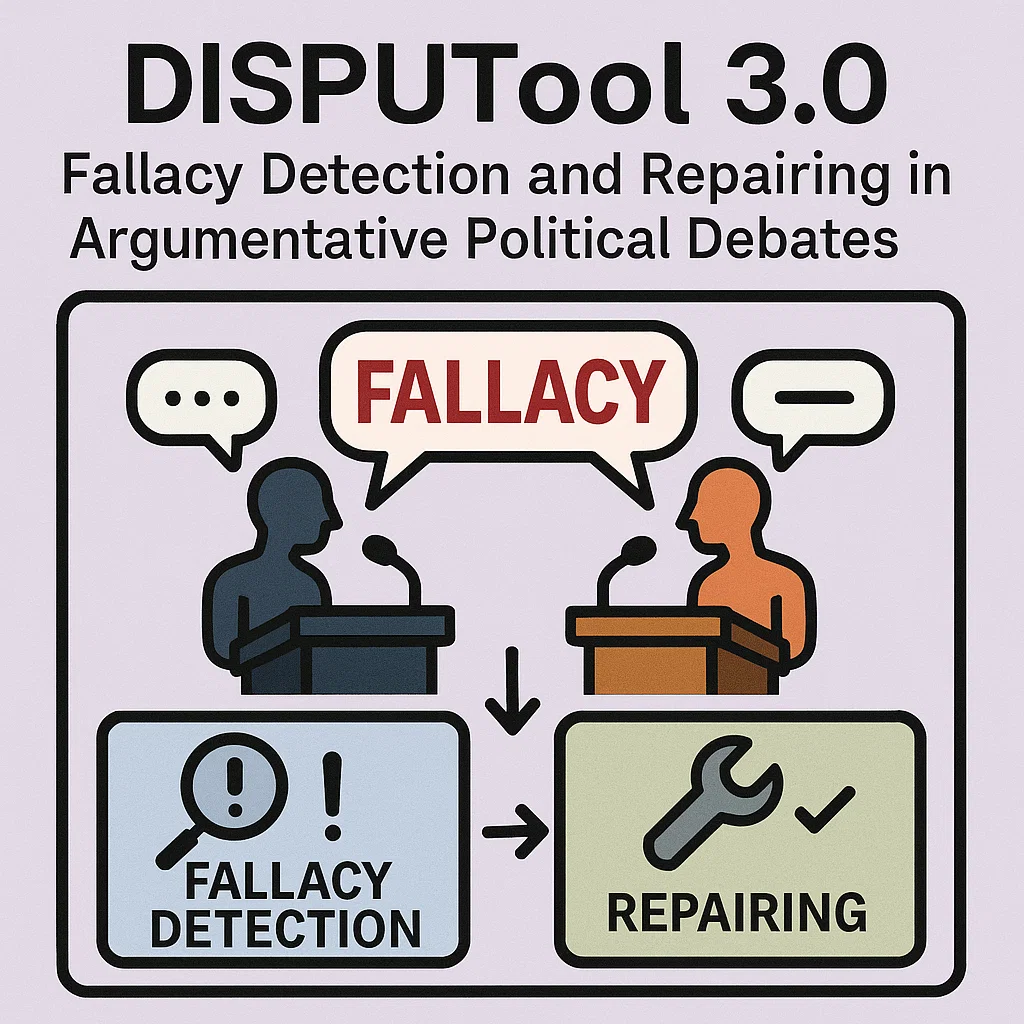 DISPUTool 3.0: Fallacy Detection and Repairing in Argumentative Political DebatesPierpaolo Goffredo, Deborah Dore, Elena Cabrio, and Serena VillataIn Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 3: System Demonstrations), ACL 2025, Vienna, Austria, July 27 - August 1, 2025, 2025
This paper introduces and evaluates a novel web-based application designed to identify and repair fallacious arguments in political debates. DISPUTool 3.0 offers a comprehensive tool for argumentation analysis of political debate, in- tegrating state-of-the-art natural language pro- cessing techniques to mine and classify argu- ment components and relations. DISPUTool 3.0 builds on the ElecDeb60to20 dataset, cover- ing US presidential debates from 1960 to 2020. In this paper, we introduce a novel task which is integrated as a new module in DISPUTool, i.e., the automatic detection and classification of fal- lacious arguments, and the automatic repairing of such misleading arguments. The goal is to show to the user a tool which not only identifies fallacies in political debates, but it also shows how the argument looks like once the veil of fallacy falls down. An extensive evaluation of the module is addressed employing both auto- mated metrics and human assessments. With the inclusion of this module, DISPUTool 3.0 ad- vances even more user critical thinking in front of the augmenting spread of such nefarious kind of content in political debates and beyond. The tool is publicly available here: https: //3ia-demos.inria.fr/disputool/
-
 Repairing Fallacious Argumentation in Political DebatesPierpaolo Goffredo, Deborah Dore, Elena Cabrio, and Serena VillataIn Argumentation in the Digital Society: Proceedings of the 5th European Conference on Argumentation, Sep 2025
Fallacious arguments are defined as “invalid” arguments (e.g., the conclusion does not follow from the premises) or wrong moves in argumentative discourse. This kind of argumentation is therefore misleading or deceptive, in particular when employed in political debates. As the spreading of this nefarious content severely impacts the society and the decision-making of both citizens and policymakers, it is vital to prevent fallacious and propagandist arguments to circulate. To address this challenging task, several approaches proposing to identify fallacious argumentation in text have been presented in the literature. However, merely identifying this content is insufficient to ensure the audience realizes the impact of the fallacious argument on its deliberation process and to support the development of critical thinking skills. To tackle this challenging goal, it is necessary to unveil why a particular argument is fallacious and to demonstrate how it could be repaired as a valid, non-fallacious argument. In this paper, we address this key challenge by proposing a new task called repairing fallacious argumentation. The goal of this task is to modify statements that contain fallacious arguments into versions that are clearer, fairer, and free from any technique that could negatively persuade listeners. We carry out this task on political debates, where the need for this kind of solution is urgent. Our contribution in addressing this task is manifold: i) a novel dataset, FallacyFix, comprising repaired examples across various fallacy categories (Appeal to Fear, Appeal to Pity, Appeal to Popular Opinion, Flag Waving, and Loaded Language) based on the ElecDeb60to20-fallacy dataset; ii) modular prompt techniques for generating non-fallacious arguments, both dependent and in- dependent of the specific fallacy label being addressed. Through an extensive evaluation, we assess these techniques using the most widely used Large Language Models (in Zero-Shot, Few-Shot, and Fine-Tuning settings) and a standard baseline model (BART); iii) a rigorous evaluation framework to assess the accuracy of the generated non-fallacious argument repairing the fallacy in the original argument, with respect to the manually annotated benchmark of non-fallacious arguments we built from the ElecDeb60to20 dataset; iv) a human evaluation of the generated non-fallacious arguments to assess the acceptability of these arguments across three dimensions, i.e., Relevance, Suitability, and Cogency. Future research will focus on integrating domain-specific knowledge to address complex fallacy categories, further analyzing language models’ behavior in countering fallacies, and exploring real-time fallacy repair methodologies. These efforts aim to enhance our ability to address fallacies dynamically in various argumentation contexts, potentially improving the quality of public discourse and decision-making.